@audio/
Status calibrated
npm3.4.0licenseMIT
Audio-facing filters — umbrella for @audio/filter-* atoms (biquads, comb, resonator, DC blocker, pre-emphasis, spectral tilt, analog ladder models)
Overview
- Install
- Updated
- Family
- 16 packages under it
- Tags
- shape
- Standards
- IEC 61672-1, ITU-R BS.1770-4, EBU R 128, ITU-R BS.468-4, IEC 60098
Canonical audio filter implementations.
|
Effect Biquad kernel Moved elsewhere (Weighting · Auditory · EQ) — see each section for the new package. |
Install
// import everything
import * as filter from '@audio/filter'

// import by domain
import { aWeighting, kWeighting } from '@audio/weighting'
import { gammatone, melBank } from '@audio/auditory'
import { moogLadder, oberheim } from '@audio/filter'
import vocoder from '@audio/speech-vocoder'
import { lpcAnalysis } from '@audio/speech-lpc'
import { parametricEq, crossover, baxandall, tilt, lowShelf, highShelf } from '@audio/eq'
import { dcBlocker, notch, lowpass, highpass, bandpass, resonator } from '@audio/filter'
API
Most filters share one shape:
filter(buffer, params) // → buffer (modified in-place)
Takes an Array/Float32Array/Float64Array, modifies it in-place, returns it. Pass the same params object on every call to persist state across blocks automatically:
import { moogLadder } from '@audio/filter'

let params = { fc: 1000, resonance: 0.5, fs: 44100 }
for (let buf of stream) moogLadder(buf, params)
Three families, by shape:
- In-place, single buffer —
filter(buffer, params) → buffer. The majority: weighting, analog, effect, most of EQ. - In-place, dual buffer —
filter(bufA, bufB, params) → { ... }.crossfeed(left, right, params),vocoder(carrier, modulator, params)— two channels/signals interact, so neither buffer alone is the whole story. - Designers/analyzers — take no buffer, return descriptor/SOS data instead of processing anything:
octaveBank,erbBank,barkBank,melBank,crossover,lpcAnalysis. Feed their output todigital-filter'sfilter()or tolpcSynthesize.
For frequency analysis, weighting filters expose a .coefs(fs) method returning a second-order sections (SOS) array — [{b0, b1, b2, a1, a2}, ...], one biquad per section — for use with digital-filter:
import { aWeighting } from '@audio/weighting'
import { freqz, mag2db } from 'digital-filter'

let sos  = aWeighting.coefs(44100)
let resp = freqz(sos, 2048, 44100)
let db   = mag2db(resp.magnitude)
Weighting
Standard measurement curves (A/C/K/ITU-468/RIAA) — moved to their own repo in the 2026-07 family split.
Now lives at: github.com/audiojs/weighting · npm install @audio/weighting
Migration: import { aWeighting } from '@audio/filter' → import { aWeighting } from '@audio/weighting'
Auditory
Cochlear/auditory-system models (gammatone, octave/ERB/Bark/mel banks) — moved to their own repo in the 2026-07 family split.
Now lives at: github.com/audiojs/auditory · npm install @audio/auditory
Migration: import { gammatone } from '@audio/filter' → import { gammatone } from '@audio/auditory'
Analog
Discrete-time models of analog circuits — each named after the hardware it replicates. Nonlinear, stateful, process in-place. The filters in synthesizers.
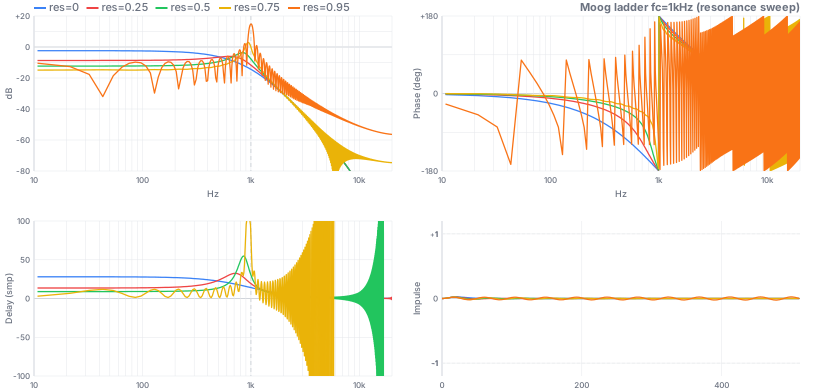
Resonance means something different per filter — all four take resonance in 0–1, but the mapping and self-oscillation point differ: moogLadder maps , self-oscillates exactly at resonance=1, at itself (each stage turns 45° there); diodeLadder uses the same but self-oscillation shifts to ≈1.15–1.2 because its extra per-stage adds damping; korg35 maps and never self-oscillates at any value — 2 real poles can't reach the −180° loop phase Barkhausen's criterion needs at any finite, audible frequency, so resonance only adds damping/saturation character; oberheim maps (inverted — resonance=1 gives , maximum SVF resonance), with bandpass peak gain exactly .
drive (default 1, all four filters) is input gain into each filter's saturation path — drive: 0 mutes the signal () rather than disabling saturation and falling back to a linear filter.
Moog ladder
Robert Moog's 4-pole transistor ladder, 1965 — the most imitated filter in electronic music.
Circuit: 4 cascaded one-pole transistor ladder sections, global feedback from output to input
Implementation: Zero-delay feedback (ZDF) via trapezoidal integration — Zavalishin (2012)[^9], Ch. 6
Response: lowpass; resonance peak at ; self-oscillation (sine wave) at resonance=1, at
Modes: type lowpass, highpass or bandpass, poles 4 or 2 — the ladder's taps mixed by binomial weights, highpass, bandpass (Zavalishin §5.5; JUCE's LadderFilter modes, Pedalboard's)
Nonlinearity: saturation at input (transistor ladder characteristic)
import { moogLadder } from '@audio/filter'

let params = { fc: 800, resonance: 0.7, fs: 44100 }
moogLadder(buffer, params)

// Self-oscillation — runs indefinitely from a single impulse
let silent = new Float64Array(4096); silent[0] = 0.01
moogLadder(silent, { fc: 1000, resonance: 1, fs: 44100 })

// Highpass, -12 dB/oct
moogLadder(buffer, { fc: 300, resonance: 0.4, fs: 44100, type: 'highpass', poles: 2 })
Patent: Moog (1965) US3475623[^10]
vs Diode ladder: Moog saturates only at input; diode saturates at each stage — different character at high resonance
Diode ladder
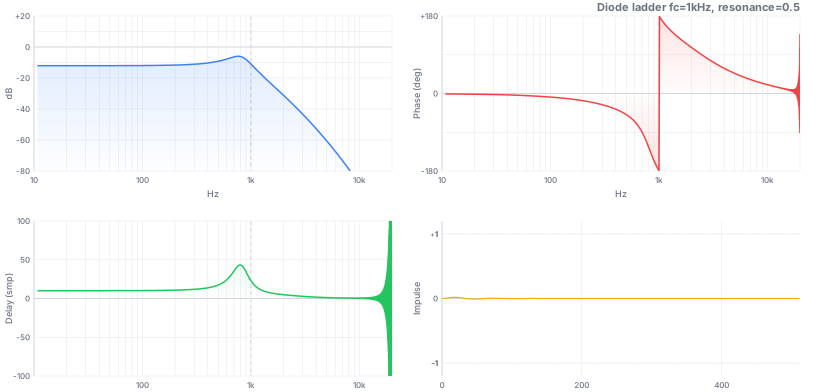
Roland TB-303 / EMS VCS3 style — per-stage saturation gives the characteristic acid "squelch".
Circuit: Roland TB-303, EMS VCS3, EDP Wasp
Key difference from Moog: stages are bidirectionally coupled — no unity-gain buffers between them (unlike Moog), so each stage loads its neighbors; solved as one tridiagonal system per sample (Thomas algorithm) instead of Moog's simple forward cascade
Character: more "squelchy"/aggressive than Moog due to the per-stage ; its coupled stages roll off below ; DC gain , as Moog's
Implementation: ZDF — Zavalishin (2012)[^9]; Pirkle (2019)[^11], Ch. 10
Stability: bounded (per-stage -saturated) across the documented 0–1 range and well beyond; self-oscillates near resonance≈1.15–1.2 — higher than Moog's exact 1, since the extra per-stage adds damping
import { diodeLadder } from '@audio/filter'

let params = { fc: 500, resonance: 0.8, fs: 44100 }
diodeLadder(buffer, params)
Korg35
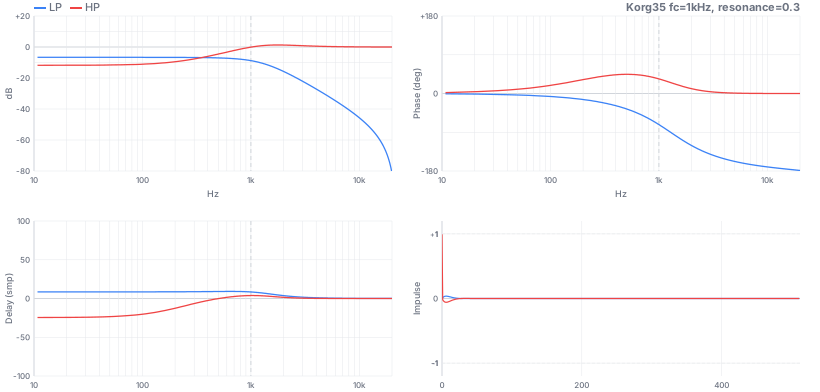
Korg MS-10/MS-20, 1978 — 2-pole filter with lowpass and highpass outputs from nonlinear feedback.
Topology: 2 cascaded one-pole sections with nonlinear feedback; HP = input − LP
Response: ; resonance 0–1 adds damping/saturation character — no resonant peak, no self-oscillation at any setting (2 real poles in the loop can't reach the −180° phase Barkhausen's criterion needs at any finite, audible frequency, unlike Moog/Diode's 4-pole loops)
Complementarity: LP+HP=input holds exactly only at resonance=0 (verified to 1e-16); at resonance>0 the HP tap's extra feedback term makes LP+HP diverge from the input (measured −7.5 dB to +1.4 dB error at resonance=0.8 across 200 Hz–5 kHz)
import { korg35 } from '@audio/filter'

korg35(buffer, { fc: 1000, resonance: 0.5, type: 'lowpass',  fs: 44100 })
korg35(buffer, { fc: 1000, resonance: 0.5, type: 'highpass', fs: 44100 })
Circuit: Korg MS-10/MS-20 (1978)
Analysis: Stilson & Smith (1996)[^12]; Zavalishin (2012)[^9], Ch. 5
vs Moog ladder: 2-pole () vs 4-pole (); Korg35 has both LP and HP taps from one circuit, but no self-oscillation
Oberheim
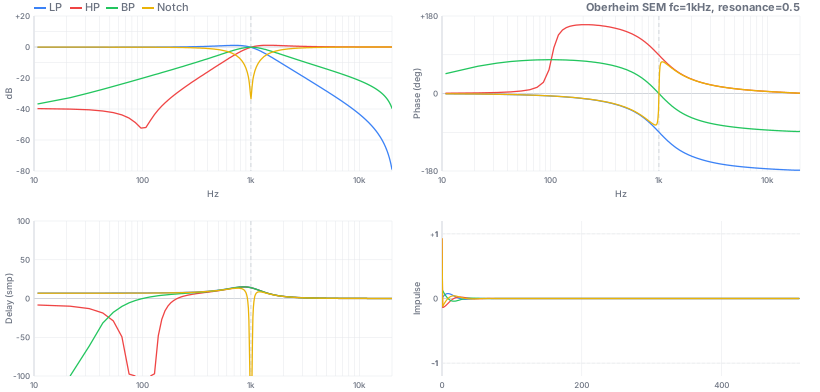
Oberheim SEM (1974) — 2-pole state-variable filter with four modes from one circuit.
Topology: 2 trapezoidal integrators with nonlinear feedback; multimode output (LP/HP/BP/notch)
Response: ; warm, musical resonance; continuous mode morphing
Implementation: ZDF — Zavalishin (2012)[^9], Ch. 4–5; saturation on integrator states
import { oberheim } from '@audio/filter'

oberheim(buffer, { fc: 1000, resonance: 0.5, type: 'lowpass',  fs: 44100 })
oberheim(buffer, { fc: 1000, resonance: 0.5, type: 'highpass', fs: 44100 })
oberheim(buffer, { fc: 1000, resonance: 0.5, type: 'bandpass', fs: 44100 })
oberheim(buffer, { fc: 1000, resonance: 0.5, type: 'notch',    fs: 44100 })
Circuit: Oberheim SEM (1974), Two Voice, Four Voice, Eight Voice
vs Moog/Korg: 2-pole like Korg35 but true state-variable topology; LP/HP/BP/notch from one circuit; warmer resonance character
Speech
Filters that model or process the human vocal tract — from vowel synthesis to spectral voice coding.
Formant
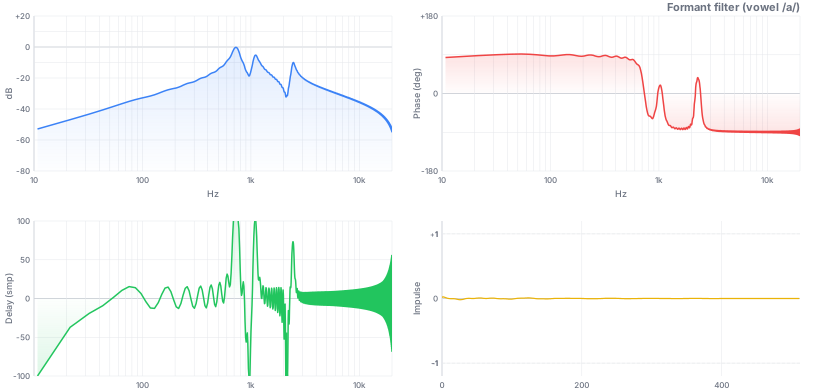
Parallel resonator bank — each peak models one vocal tract resonance (formant).
Model: parallel combination of second-order resonators, each modeling one vocal tract mode
Formant frequencies: determined by vocal tract shape; F1 controls vowel openness, F2 controls front/back
Typical ranges: F1: 250–850 Hz, F2: 850–2500 Hz, F3: 1700–3500 Hz
Implementation: uses resonator internally — constant peak-gain bandpass per formant
Defaults: F1=730 Hz, F2=1090 Hz, F3=2440 Hz (open vowel /a/)
import formant from '@audio/speech-formant'

formant(excitation, { fs: 44100 })   // vowel /a/ (default)

formant(excitation, {
  formants: [{ fc: 270, bw: 60, gain: 1 }, { fc: 2290, bw: 90, gain: 0.5 }],
  fs: 44100
})   // vowel /i/
Use when: speech synthesis, singing synthesis, vocal effects, acoustic phonetics
Not a substitute for: LPC synthesis, which estimates formants automatically from a speech signal
Vocoder
Channel vocoder — transfers the spectral envelope of one sound onto the pitched content of another.
Note: takes two separate buffers, returns a new buffer (does not modify in-place).
Principle: analyze modulator into N bands → extract envelope per band → multiply with filtered carrier → sum
Implementation: N parallel bandpass filters on both signals; envelope follower per modulator band
Band count: 8 = robotic effect; 16 = classic vocoder sound; 32+ = more speech intelligibility
import vocoder from '@audio/speech-vocoder'

// carrier: pitched source (sawtooth, buzz, noise...)
// modulator: signal whose spectral shape to impose (voice, instrument...)
let output = vocoder(carrier, modulator, { bands: 16, fs: 44100 })
Inventor: Dudley (1939)[^13], Bell Labs
Use when: voice effects, talkbox simulation, cross-synthesis, spectral morphing
LPC
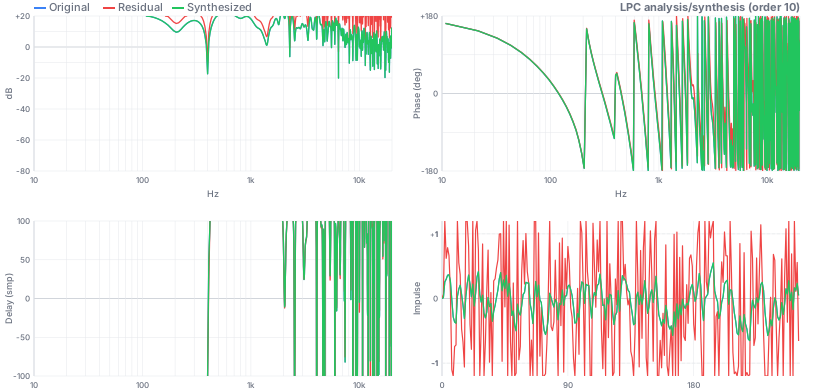
Linear Predictive Coding — estimates the vocal tract transfer function from a speech signal.
Analysis: autocorrelation method + Levinson-Durbin recursion → LPC coefficients + residual
Synthesis: all-pole filter reconstructs signal from residual excitation
Round-trip: lpcAnalysis → lpcSynthesize recovers the original signal exactly
import { lpcAnalysis, lpcSynthesize } from '@audio/speech-lpc'

// Analysis: extract vocal tract model
let { coefs, gain, residual } = lpcAnalysis(speechFrame, { order: 12 })

// Synthesis: reconstruct from residual
lpcSynthesize(residual, { coefs, gain })   // residual → reconstructed speech

// Modify pitch: replace residual with different excitation
let buzz = generatePulseTrainAtNewPitch()
lpcSynthesize(buzz, { coefs, gain })       // speech at new pitch
Origin: Atal & Hanauer (1971)[^19]; foundation of CELP, GSM, and modern speech codecs
Use when: speech coding, pitch modification, voice conversion, formant estimation, speech analysis
EQ
Studio EQ (graphic, parametric, crossover, shelving, Baxandall, tilt) — moved to its own repo in the 2026-07 family split. Crossfeed moved separately, to spatial.
EQ now lives at: github.com/audiojs/eq · npm install @audio/eq
Crossfeed now lives at: github.com/audiojs/spatial · npm install @audio/spatial (atom: @audio/spatial-crossfeed)
Migration: import { parametricEq, crossfeed } from '@audio/filter' → import { parametricEq } from '@audio/eq' + import { crossfeed } from '@audio/spatial'
Effect
Signal conditioning and spectral shaping — single-purpose filters with well-defined transfer functions.
DC blocker
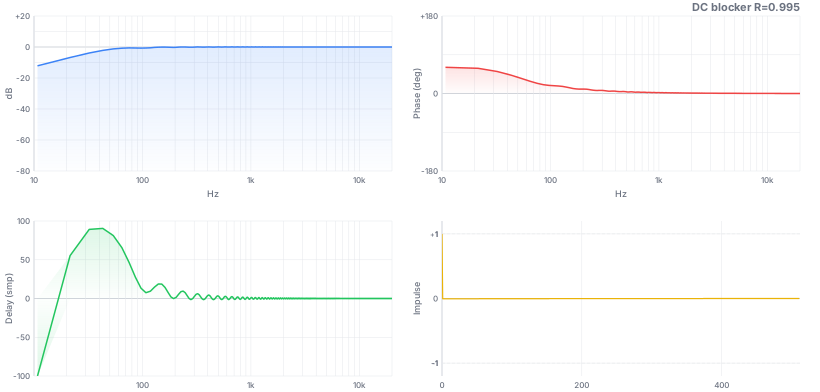
Removes DC offset — the simplest useful filter.
Topology: zero at (DC), pole at
Cutoff: — gives ~35 Hz at 44.1 kHz
import { dcBlocker } from '@audio/filter'

let params = { R: 0.995 }
dcBlocker(buffer, params)
Use when: removing DC bias before processing, preventing lowpass filter saturation
Comb filter
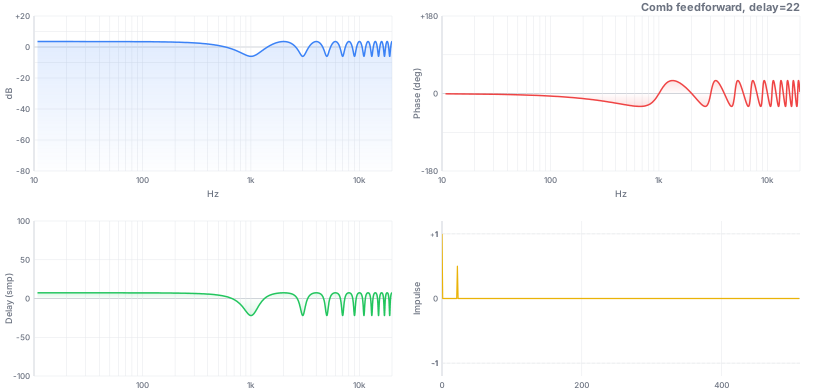
Adds a delayed copy of the signal to itself — notches and peaks at harmonics of .
Feedforward: — dips at , depth depends on : a true null only at ; the default gives a dip, not a notch
Feedback: — peaks at
import { comb } from '@audio/filter'

comb(buffer, { delay: 100, gain: 0.6, type: 'feedback' })
Use when: flanging, chorus (with modulated delay), Karplus-Strong string synthesis, room mode modeling
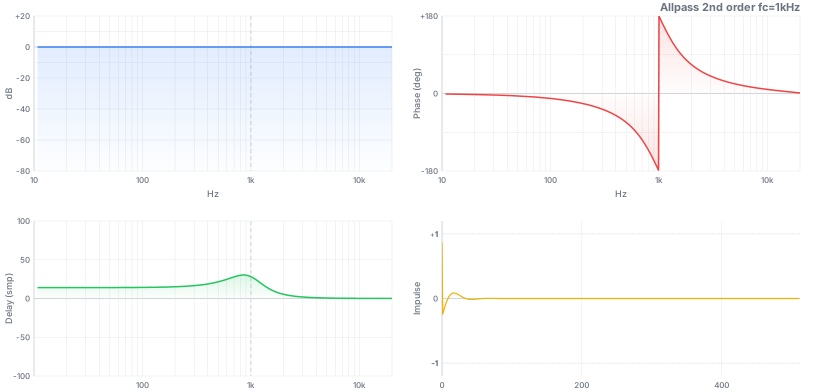
Allpass
Unity magnitude at all frequencies — shifts phase only. First and second order.
First order: — pole at , 180° phase shift at Nyquist
Second order: , — RBJ cookbook allpass; 360° phase shift around , width of the transition controlled by
import { allpass } from '@audio/filter'

allpass.first(buffer, { a: 0.5 })                          // coefficient a
allpass.second(buffer, { fc: 1000, Q: 1, fs: 44100 })      // center fc, quality Q
Use when: phase equalization, reverb building blocks (Schroeder reverb), stereo widening
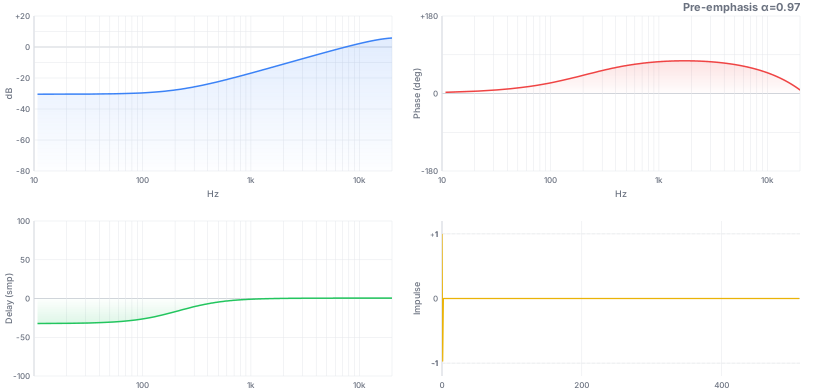
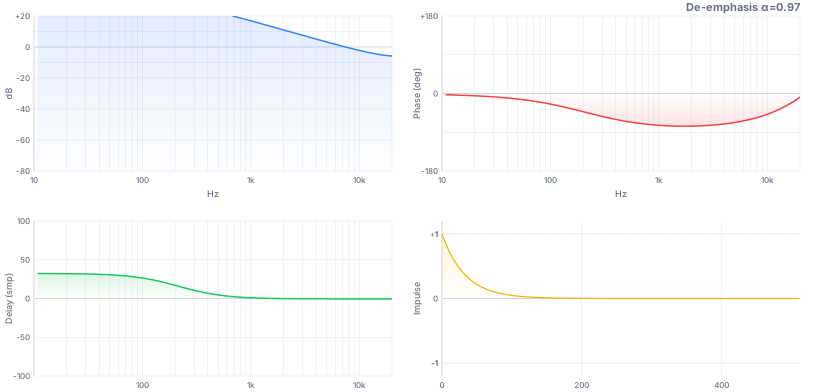
Pre-emphasis / de-emphasis
First-order highpass (emphasis) and its inverse (de-emphasis) — used before and after coding or transmission.
(emphasis) / (de-emphasis)
Rolloff: emphasis boosts above — gives ~210 Hz at 44.1 kHz
Inverse pair: deemphasis exactly cancels emphasis — (round-trip error ~5.5e-17)
import { emphasis, deemphasis } from '@audio/filter'

emphasis(buffer, { alpha: 0.97 })    // before encoding
deemphasis(buffer, { alpha: 0.97 })  // after decoding — exact inverse
Use when: speech coding (GSM, AMR uses ), tape recording, FM broadcasting
Derivative / integral
First-difference and running-sum — an exact inverse pair (FFmpeg's aderivative/aintegral).
(derivative) / (integral, leak=1)
Inverse pair: integral at leak: 1 exactly reconstructs the input passed to derivative — the running sum telescopes
Leak: leak < 1 bleeds the accumulator per sample so DC-biased material converges to a finite value () instead of drifting
import { derivative, integral } from '@audio/filter'

derivative(buffer, {})
integral(buffer, { leak: 1 })    // 1 = exact FFmpeg aintegral; <1 for stability on real program material
Use when: edge/transient detection (derivative), reconstructing a signal from its differenced form (integral), envelope-adjacent accumulation
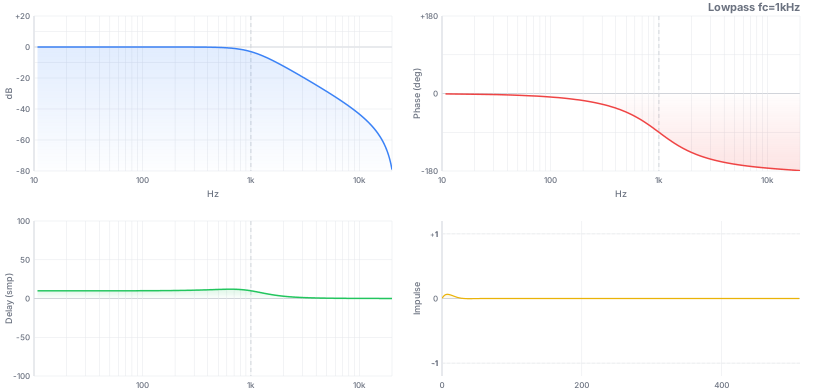
Lowpass
Removes everything above cutoff frequency — the most common filter in audio.
Order 2 (default): RBJ biquad lowpass —
Order 4+: Butterworth cascaded SOS — where = order; requires registering digital-filter's Butterworth designer once (kept out of the default import so lowpass/highpass stay lean when you only need order 2)
import { lowpass } from '@audio/filter'
import butterworth from 'digital-filter/iir/butterworth.js'

lowpass.useButterworth(butterworth)   // once, before any order > 2 call

lowpass(buffer, { fc: 2000, fs: 44100 })                // 2nd-order (default) — no registration needed
lowpass(buffer, { fc: 2000, order: 4, fs: 44100 })      // 4th-order Butterworth
lowpass(buffer, { fc: 2000, Q: 1.5, fs: 44100 })        // resonant
Use when: anti-aliasing, smoothing, removing hiss, synth subtractive filtering
vs Moog ladder: lowpass is a clean linear filter; Moog adds nonlinear saturation and self-oscillation
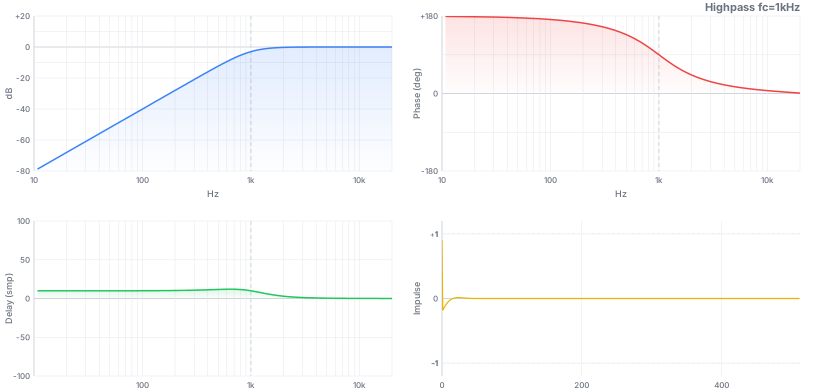
Highpass
Removes everything below cutoff frequency — DC removal, rumble elimination.
Order 2 (default): RBJ biquad highpass —
Order 4+: Butterworth cascaded SOS — where = order; same registration as Lowpass above
import { highpass } from '@audio/filter'
import butterworth from 'digital-filter/iir/butterworth.js'

highpass.useButterworth(butterworth)   // once, before any order > 2 call

highpass(buffer, { fc: 80, fs: 44100 })                 // rumble filter
highpass(buffer, { fc: 80, order: 4, fs: 44100 })       // steeper rolloff
Use when: removing rumble, mic handling noise, subsonic content before dynamics processing
vs DC blocker: highpass has adjustable cutoff and slope; DC blocker is simpler, lighter, fixed near 0 Hz
Bandpass
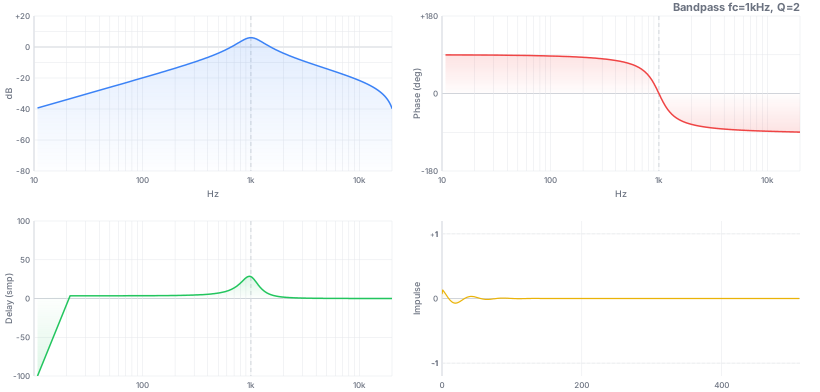
Passes frequencies around center frequency, rejects the rest — constant 0 dB peak gain.
Implementation: RBJ biquad bandpass (constant peak, Q controls width)
import { bandpass } from '@audio/filter'

bandpass(buffer, { fc: 1000, Q: 5, fs: 44100 })         // narrow
bandpass(buffer, { fc: 1000, Q: 0.5, fs: 44100 })       // wide
Use when: isolating frequency regions, radio effect, walkie-talkie simulation, band splitting
vs Resonator: bandpass is RBJ biquad (standard); resonator has constant peak gain — use resonator for modal synthesis
Resonator
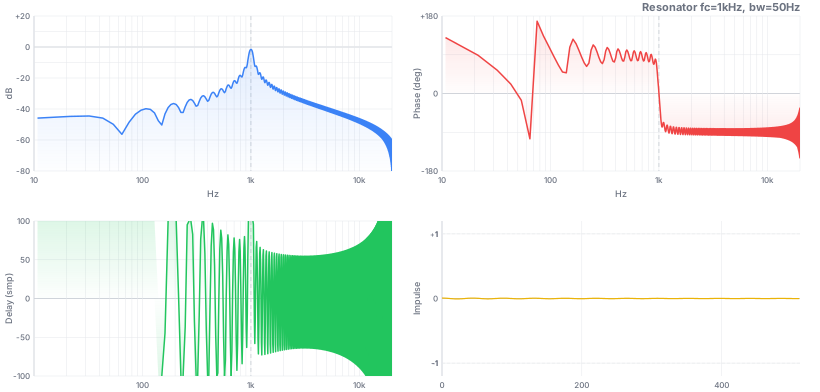
Constant peak-gain bandpass — peak amplitude stays fixed regardless of bandwidth.
Pole radius: — controls bandwidth; gives infinite Q
Peak gain: always 0 dB by construction — the two zeros at shape the numerator so normalizes the pole peak regardless of fc/bw (verified ±0.01 dB across fc ∈ {50, 440, 5000, 15000} Hz, bw ∈ {5, 20, 200} Hz)
Origin: Julius O. Smith III, "Introduction to Digital Filters" — Two-Pole, "Constant Peak-Gain Resonator"[^17]
import { resonator } from '@audio/filter'

resonator(buffer, { fc: 440, bw: 20, fs: 44100 })
Use when: additive synthesis (bells, gongs), modal synthesis, formant bank building
vs Peaking EQ: resonator has fixed 0 dB peak; peaking EQ has variable gain — use resonator for synthesis, EQ for mixing
Notch
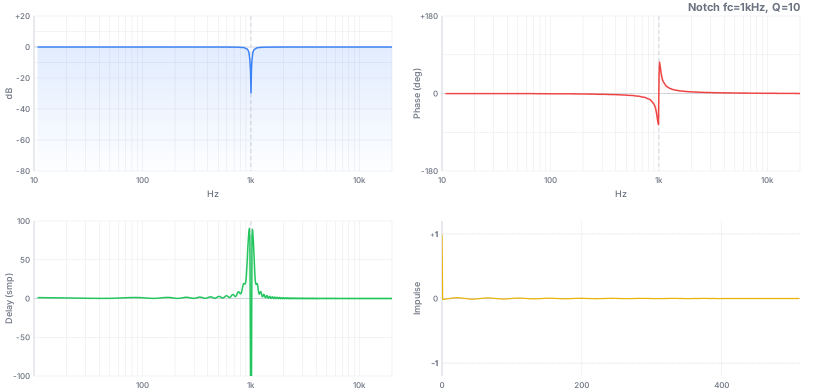
Band-reject filter — unity gain everywhere except a deep null at fc.
Q: controls notch width — is narrow (hum removal); is wider (resonance suppression)
Zeros: on the unit circle at — exact null, independent of Q
import { notch } from '@audio/filter'

notch(buffer, { fc: 50,   Q: 30, fs: 44100 })   // remove 50 Hz mains hum
notch(buffer, { fc: 1000, Q: 10, fs: 44100 })   // suppress a resonance
Use when: mains hum removal (50/60 Hz), feedback cancellation, room mode suppression
vs Parametric EQ with negative gain: notch reaches −∞ dB exactly at fc; peaking EQ has finite attenuation
Pink noise
Shapes white noise to spectrum — moved to @audio/synth (the @audio/synth-noise atom) in the 2026-07 family split; spectralTilt below (still here) is the general-purpose fractional-slope tool.
Now lives at: github.com/audiojs/synth · npm install @audio/synth
Migration: import { pinkNoise } from '@audio/filter' → import { pinkNoise } from '@audio/synth'
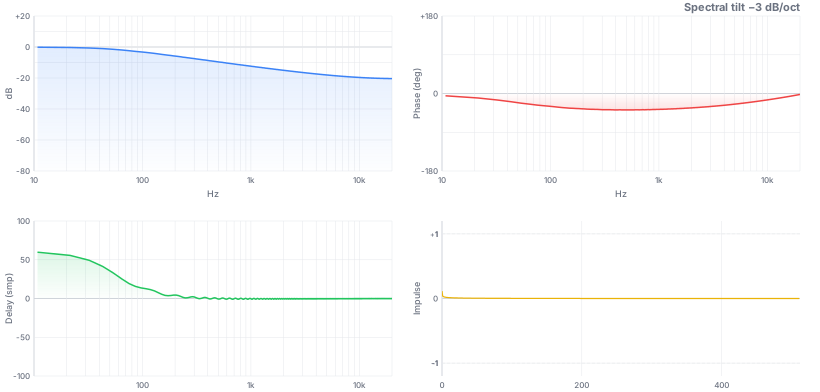
Spectral tilt
Applies a constant dB/octave slope — tilts the entire spectrum.
Model: cascade of 8 octave-spaced first-order shelving sections approximating a fractional power-law spectrum ; positive slope boosts highs, negative slope cuts them
slope: gives pink noise character; gives brownian/red noise
Accuracy: measured slope tracks the requested dB/oct to within ~20% (inherent to the 8-stage shelving cascade) — e.g. slope: +3 measures ≈+2.4 dB/oct, slope: -6 measures ≈-4.9 dB/oct
import { spectralTilt } from '@audio/filter'

spectralTilt(buffer, { slope: -3, fs: 44100 })   // −3 dB/oct: pink noise character
spectralTilt(buffer, { slope: +3, fs: 44100 })   // +3 dB/oct: pre-emphasis for coding
Use when: matching microphone/speaker frequency responses, spectral coloring, noise synthesis
Variable bandwidth
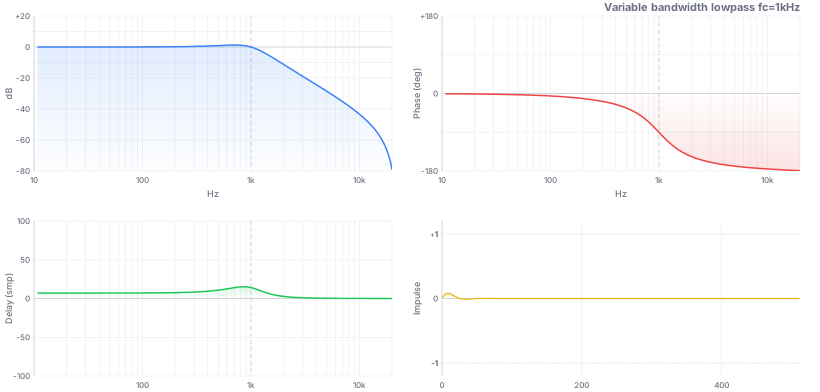
Lowpass with continuously variable bandwidth — smooth parameter automation without discontinuities.
Implementation: fc/Q are exponentially smoothed toward their target values with a 5 ms time constant, and biquad coefficients are recomputed from the smoothed values every sample (not once per buffer)
Property: no discontinuity when or change — a mid-buffer step change lands ~9x closer to the plain-lowpass baseline than an abrupt coefficient jump; once converged, steady-state output equals plain lowpass/highpass/bandpass
import { variableBandwidth } from '@audio/filter'

variableBandwidth(buffer, { fc: 2000, Q: 1.0, fs: 44100 })
Use when: LFO-modulated filter cutoff, automated EQ sweeps, smooth filter animation
vs Direct biquad: recalculating biquad coefficients per sample causes zipper noise; variable bandwidth avoids this
Biquad kernel
highpass/lowpass/bandpass/notch/allpass above are built on @audio/filter-biquad, which itself wraps the shared @audio/biquad kernel — one coefficient/state source for every biquad-shaped atom in the @audio ecosystem (RBJ cookbook coefficients, Web Audio conventions, transposed direct-form-II state).
import { lowpass, peaking, filter, process, state, cascade, magnitude } from '@audio/biquad'

let c = lowpass(1000, 0.707, 44100)   // coefficients — normalized a0 = 1
filter(chunk, { coefs: [c] })         // params-convention: state rides the params object

let s = process(chunk, c, state())    // section-level kernel, explicit state
magnitude(c, 440, 44100)              // |H(f)| — analysis/plotting
Use when: building a new biquad-shaped atom, or bypassing filter-biquad's Hz/Q wrapper for raw coefficient/state control
See: github.com/audiojs/filter/tree/main/packages/biquad
Filter selection guide
| I need to... | Use |
|---|---|
| Synth filter — warmth and resonance | moogLadder |
| Synth filter — acid / squelch | diodeLadder |
| Synth filter — 2-pole LP + HP | korg35 |
| Synth filter — multimode SVF | oberheim |
| Synthesize vowel sounds | formant |
| Transfer one sound's spectral shape to another | vocoder |
| Analyze/resynthesize speech, change pitch | lpcAnalysis / lpcSynthesize |
| Remove DC offset | dcBlocker |
| Remove mains hum / suppress resonance | notch |
| Clean lowpass / anti-alias | lowpass |
| Remove rumble / subsonic content | highpass |
| Isolate a frequency band | bandpass |
| Create resonant combing | comb |
| Phase-shift without changing magnitude | allpass.first, allpass.second |
| Pre-process for audio coding | emphasis / deemphasis |
| Modal synthesis (bells, drums, rooms) | resonator |
| Tilt spectrum for noise synthesis | spectralTilt |
| Smooth automated filter sweeps | variableBandwidth |
| Build a custom biquad-shaped atom | @audio/biquad kernel (coefficients + SOS state) |
Measurement curves, auditory banks, studio EQ, crossfeed, and colored noise moved out of this repo — see Weighting, Auditory, EQ, and each section's pointer for the replacement package.
FAQ
Why does my filter click when I change fc or Q?
Biquad coefficients change discontinuously between samples. Use variableBandwidth for smooth automated sweeps, or crossfade.
Why does my Moog/Diode filter blow up?
resonance=1 on Moog is intentional self-oscillation. Diode ladder is bounded across its full resonance range (per-stage -saturated); it self-oscillates near resonance≈1.15–1.2, not exactly at 1 like Moog. Limit input gain before high resonance.
Does mutating params between calls reset state?
No — mutating the same object (params.fc = newFc) preserves state. Replacing the object (params = { fc: newFc }) loses it.
Recipes
Chain filters
import { dcBlocker } from '@audio/filter'
import { moogLadder } from '@audio/filter'

let p1 = { fc: 200, fs: 44100 }
let p2 = { R: 0.995 }
for (let buf of stream) {
  dcBlocker(buf, p2)   // DC removal first
  moogLadder(buf, p1)
}
Stereo — independent state per channel
import { moogLadder } from '@audio/filter'

let pL = { fc: 1000, fs: 44100 }
let pR = { fc: 1000, fs: 44100 }
for (let [L, R] of stereoStream) {
  moogLadder(L, pL)
  moogLadder(R, pR)
}
Notch out mains hum
import { notch } from '@audio/filter'

let p = { fc: 50, Q: 30, fs: 44100 }
for (let buf of stream) notch(buf, p)   // removes 50 Hz hum, flat elsewhere
Automate cutoff without clicks
import { variableBandwidth } from '@audio/filter'

let p = { fc: 200, Q: 1.0, fs: 44100 }
for (let buf of stream) {
  p.fc = 200 + lfo() * 1800   // mutate in-place — state preserved
  variableBandwidth(buf, p)
}
Pitfalls
New params object on every call — state resets each block
// Wrong
for (let buf of stream) moogLadder(buf, { fc: 1000, fs: 44100 })

// Right — create once, reuse
let p = { fc: 1000, fs: 44100 }
for (let buf of stream) moogLadder(buf, p)
Shared params for stereo — channels corrupt each other's state
// Wrong
let p = { fc: 1000, fs: 44100 }
for (let [L, R] of stream) { moogLadder(L, p); moogLadder(R, p) }

// Right — one object per channel
let pL = { fc: 1000, fs: 44100 }, pR = { fc: 1000, fs: 44100 }
for (let [L, R] of stream) { moogLadder(L, pL); moogLadder(R, pR) }
Filtering the same buffer twice for multi-band — second band sees pre-filtered input
// Wrong
filter(buffer, { coefs: bands[0] })
filter(buffer, { coefs: bands[1] })   // input already filtered!

// Right — copy per band
let bufs = bands.map(b => { let c = Float64Array.from(buffer); filter(c, { coefs: b.coefs }); return c })
Omitting fs — silently uses 44100 Hz math on 48000 Hz audio
// Wrong — wrong cutoffs at 48 kHz
moogLadder(buffer, { fc: 1000 })

// Right
moogLadder(buffer, { fc: 1000, fs: 48000 })
See also
- effect — audio effects: phaser, flanger, chorus, wah, compressor, reverb, delay, and more
- digital-filter — general-purpose filter design: Butterworth, Chebyshev, Bessel, Elliptic, FIR, and more
- decode — decode audio files to PCM buffers
- speaker — output PCM audio to system speakers
- Web Audio API — browser built-in audio; basic biquad shapes only, requires
AudioContext
[^1]: IEC 61672-1:2013, Electroacoustics — Sound level meters — Part 1: Specifications. Supersedes IEC 651:1979.
[^2]: ITU-R BS.1770-4:2015, Algorithms to measure audio programme loudness and true-peak audio level. Adopted by EBU R128.
[^3]: ITU-R BS.468-4:1986, Measurement of audio-frequency noise voltage level in sound broadcasting. Originally CCIR 468, 1968.
[^4]: RIAA standard (1954). Cf. IEC 60098:1987, Analogue audio disk records and reproducing equipment, whose 4-time-constant variant adds a subsonic pole this implementation does not.
[^5]: Patterson, R.D., Robinson, K., Holdsworth, J., McKeown, D., Zhang, C. & Allerhand, M. (1992). "Complex sounds and auditory images." Auditory Physiology and Perception, Pergamon, pp. 429–446.
[^6]: IEC 61260-1:2014, Electroacoustics — Octave-band and fractional-octave-band filters — Part 1: Specifications. ANSI S1.11:2004.
[^7]: Moore, B.C.J. & Glasberg, B.R. (1983). "Suggested formulae for calculating auditory-filter bandwidths and excitation patterns." JASA 74(3), pp. 750–753. Updated 1990.
[^8]: Zwicker, E. (1961). "Subdivision of the audible frequency range into critical bands." JASA 33(2), p. 248.
[^9]: Zavalishin, V. (2012). The Art of VA Filter Design. Native Instruments.
[^10]: Moog, R.A. (1965). Voltage controlled electronic music modules. Patent US3475623.
[^11]: Pirkle, W.C. (2019). Designing Audio Effect Plugins in C++, 2nd ed. Routledge.
[^12]: Stilson, T. & Smith, J.O. (1996). "Analyzing the Moog VCF with considerations for digital implementation." Proc. ICMC.
[^13]: Dudley, H. (1939). "The vocoder." Bell Laboratories Record 17, pp. 122–126. Patent US2151091.
[^14]: Linkwitz, S. & Riley, R. (1976). "Active Crossover Networks for Non-Coincident Drivers." JAES 24(1), pp. 2–8.
[^15]: Bauer, B.B. (1961). "Stereophonic Earphones and Binaural Loudspeakers." JAES 9(2), pp. 148–151.
[^16]: Zölzer, U. (2011). DAFX: Digital Audio Effects, 2nd ed. Wiley.
[^17]: Smith, J.O. III. Introduction to Digital Filters with Audio Applications. "Two-Pole" — "Constant Peak-Gain Resonator". CCRMA, Stanford University. https://ccrma.stanford.edu/~jos/filters/
[^18]: O'Shaughnessy, D. (2000). Speech Communications: Human and Machine, 2nd ed. IEEE Press.
[^19]: Atal, B.S. & Hanauer, S.L. (1971). "Speech Analysis and Synthesis by Linear Prediction of the Speech Wave." JASA 50(2B), pp. 637–655.
[^20]: Baxandall, P.J. (1952). "Transistor Tone-Control Design." Wireless World 58(10), pp. 402–405.